My work sits directly between Data Science and AI Engineering. Rather
than treating machine learning models as black-box API calls, I focus on the full lifecycle: cleaning and
structuring raw data, engineering high-signal features, training and evaluating statistical and deep
learning models, and deploying them into reliable backend systems.
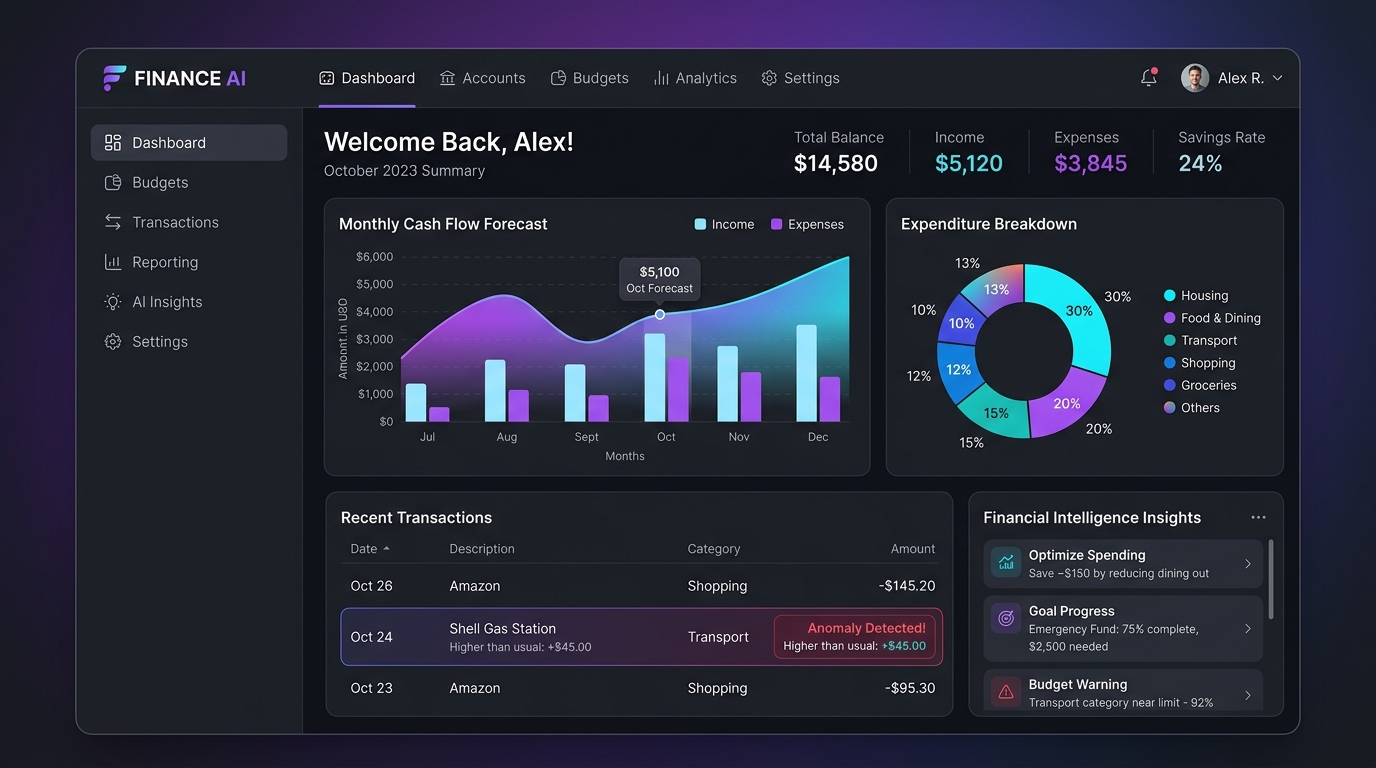
Whether I am building anomaly detection and time-series forecasting pipelines on financial data, streaming
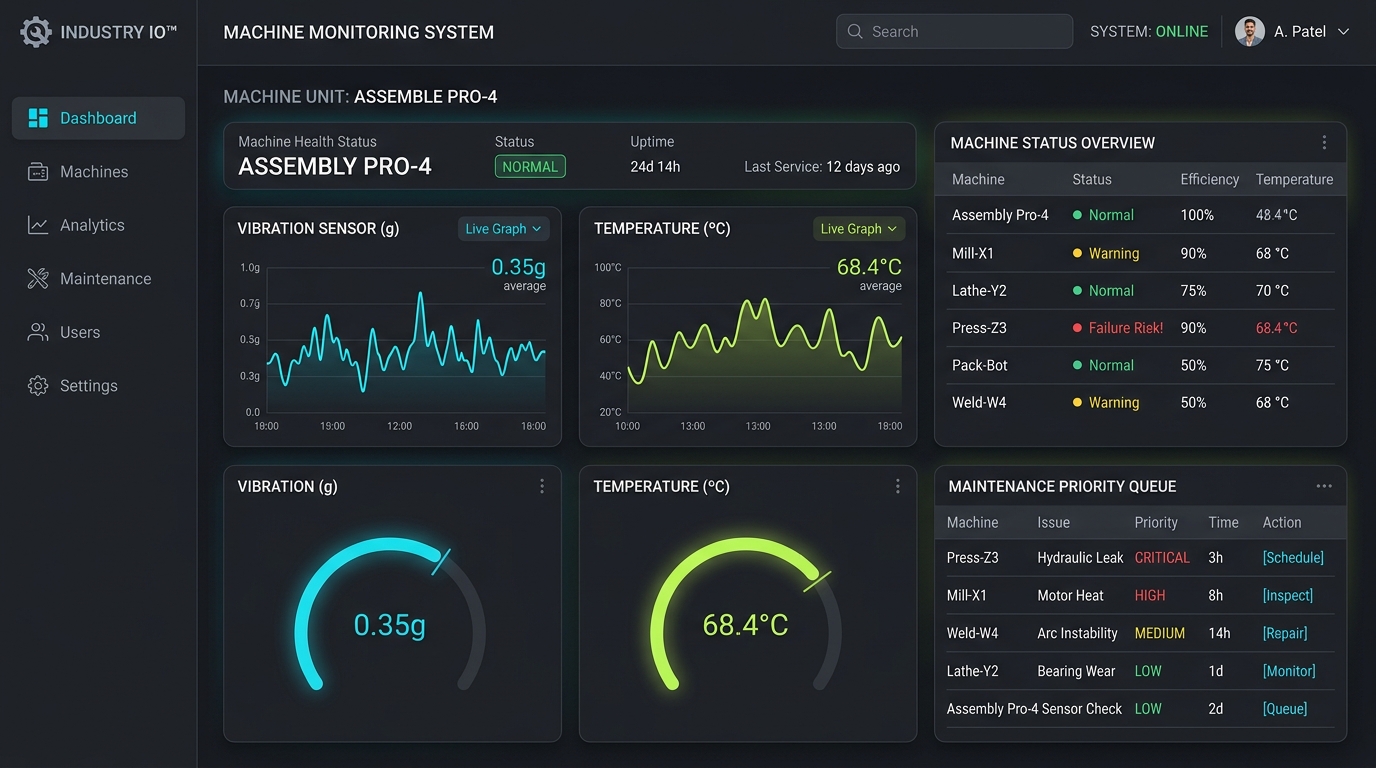
sensor telemetry into predictive maintenance classifiers, or engineering dense vector retrieval (RAG) and
LLM applications, I care about measurable accuracy and clean execution.
Alongside my engineering work here, I keep a personal Journal where I share my day-to-day life, what tech I am focusing on, photos,
voice notes, videos, and code from my daily builds.
Data Science & Predictive Modeling
Exploratory data analysis, feature engineering, supervised classification & regression, unsupervised
anomaly detection (Isolation Forests, clustering), time-series forecasting, and model evaluation with
Scikit-learn, Pandas, NumPy, and Statsmodels.
AI Engineering & LLM Systems
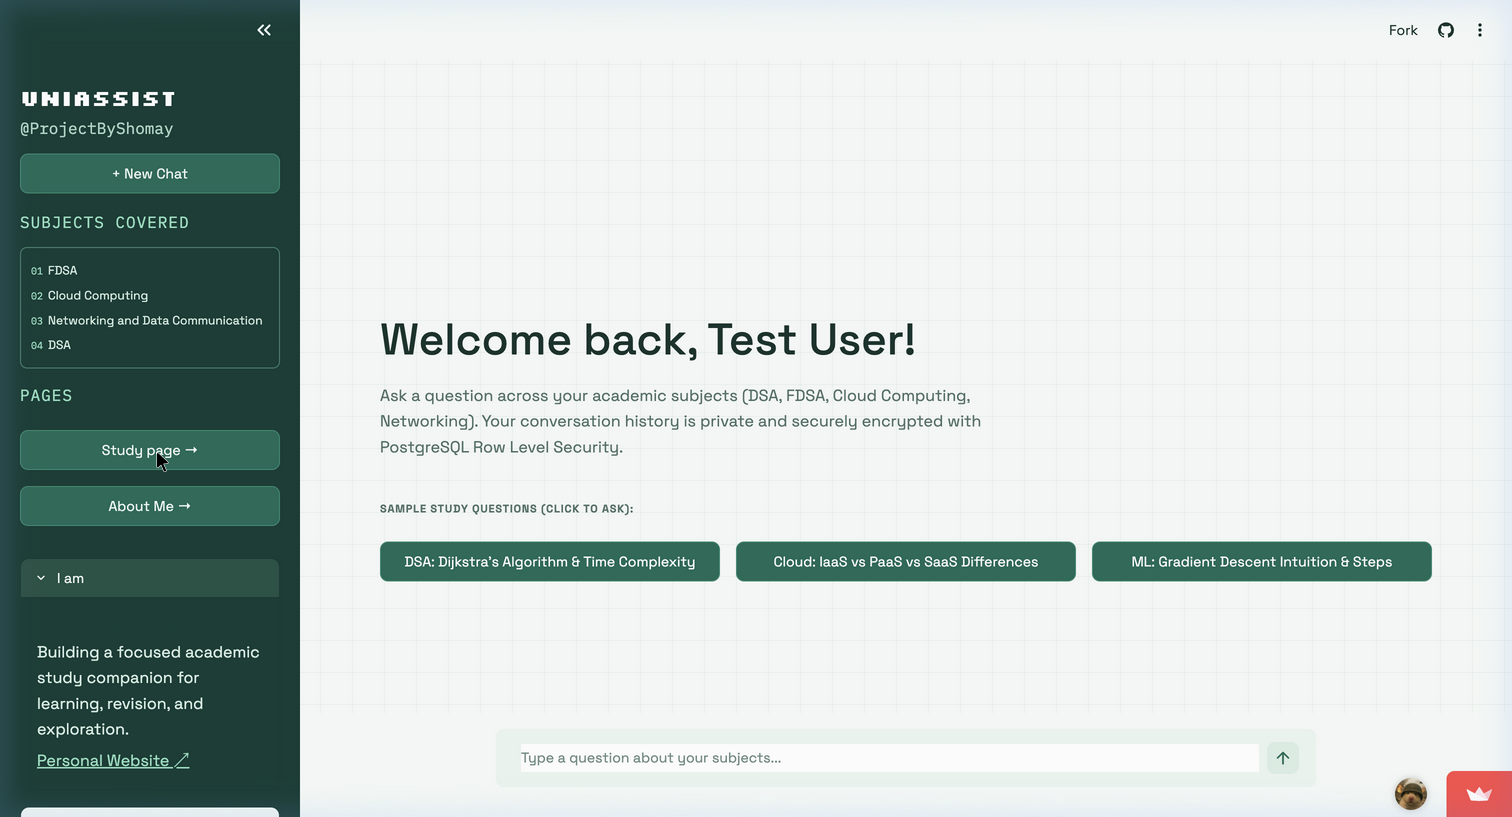
Deep learning with PyTorch and TensorFlow, Transformer architectures, dense sentence embeddings, FAISS
vector search, Retrieval-Augmented Generation (RAG), model fine-tuning, and local LLM inference.
ML Pipelines & Backend Infrastructure
Deploying models into production APIs using FastAPI, streaming real-time telemetry, managing PostgreSQL
and MongoDB data stores, and orchestrating containerized Linux deployments with Docker.